Home/Blog/The Dawn of Desktop Superintelligence: Running Qwen 3.8 Flash Next (125B) on Consumer Hardware (RTX 4090) at 100T/s
AI-native teamwork
The Dawn of Desktop Superintelligence: Running Qwen 3.8 Flash Next (125B) on Consumer Hardware (RTX 4090) at 100T/s
The Dawn of Desktop Superintelligence: Running Qwen 3.8 Flash Next (125B) on Consumer Hardware (RTX 4090) at 100T/s The landscape of artificial intelligence is rapidly evolving, pu
6 MIN READ
04 Oct 2026
AI-native teamwork
The Dawn of Desktop Superintelligence: Running Qwen 3.8 Flash Next (125B) on Consumer Hardware (RTX 4090) at 100T/s
The landscape of artificial intelligence is rapidly evolving, pushing the boundaries of what's possible on local hardware. The ability to run advanced large language models (LLMs) like Qwen 3.8 Flash Next (125B) on consumer-grade equipment, such as an RTX 4090, at speeds approaching 100 tokens per second (T/s) represents a significant leap forward. This development signals a future where sophisticated AI capabilities are not confined to data centers but are readily accessible, empowering individuals and transforming collaborative environments, including the human + AI co-working spaces found in platforms like Nonilion.
Qwen, also known as Tongyi Qianwen, is a prominent family of large and small language models (LLM and SLM) developed by Alibaba Cloud. Positioned as an AI assistant for everyone, Qwen is designed for creativity and collaboration, offering free and open access to its capabilities. The Qwen series models form the backbone of this assistant, with a strong emphasis on an open-source strategy for many of its iterations.
The evolution of Qwen models has been rapid and impactful. The first iteration, drawing from Meta AI's Llama 1, launched its beta in April 2023, subsequently releasing the weights for its 72B model in December of that year. This commitment to open weights has allowed for broader experimentation and integration.
Key models within the Qwen family include:
Qwen: The foundational series, constantly evolving.
Qwen2: An iteration building upon previous versions.
Qwen3: A further advancement in the model family.
Qwen3.8: A significant release, with a 2.4 trillion parameter model that, by August 2026, was noted as one of the largest and most powerful open weights LLMs, particularly for Chinese language processing. A distilled version, Qwen3.8 27B, was released under a more permissive Apache License, making it highly accessible for developers.
Qwen3.8 Flash Next: This specific model, along with its FP8 variant (Qwen/Qwen3.8-Flash-Next-FP8), represents a focus on speed and efficiency, crucial for achieving high inference rates on diverse hardware.
Beyond core language models, the Qwen ecosystem includes specialized applications. Qwen3Guard, for instance, is the first safety guardrail model in the Qwen family, providing real-time safety detection for prompts and responses across multiple languages. Other innovations include Qwen-Image-Edit for higher quality and efficient image editing, Qwen-Image for crafting with native text rendering, and Qwen-MT for smart translation, showcasing the breadth of Alibaba Cloud's AI and ML interests and recent activity in papers and development.
02The Quest for Local Performance: 100T/s on an RTX 4090
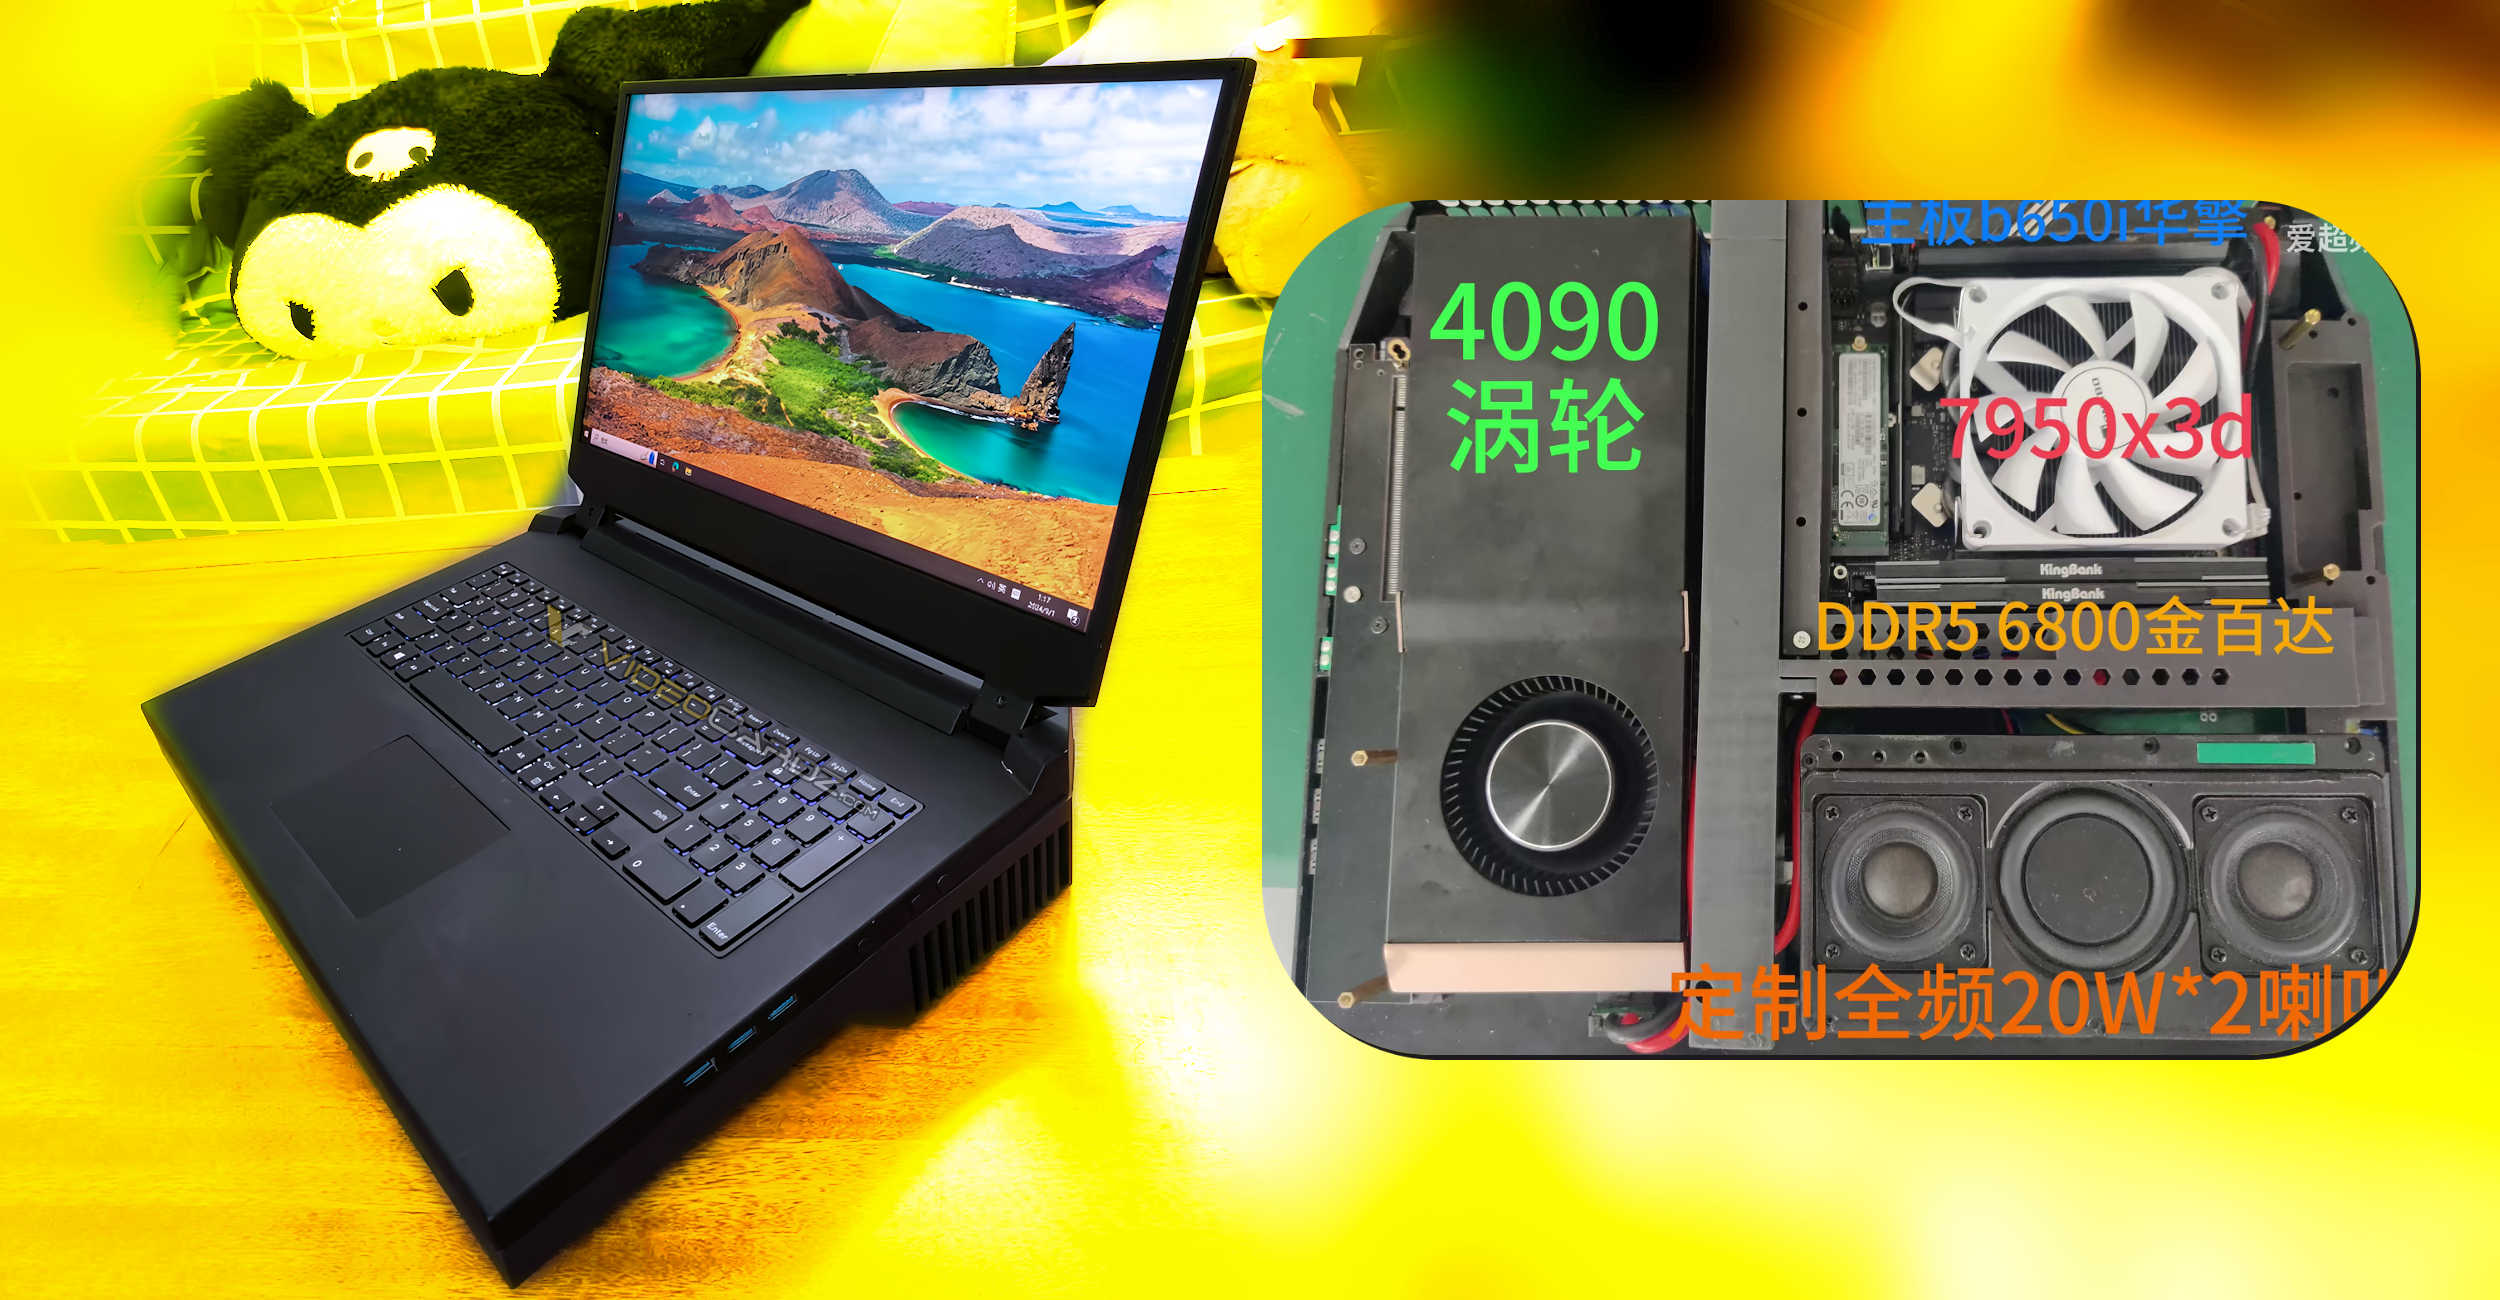
The aspiration to run Qwen 3.8 Flash Next (125B) on consumer hardware like the NVIDIA RTX 4090 at a blazing speed of 100 tokens per second (T/s) is more than just a technical benchmark; it's a paradigm shift for local AI deployment. Such performance would transform the utility of advanced LLMs, making real-time, high-volume inference a reality outside of enterprise data centers.
While achieving 100 T/s on an RTX 4090 for a 125B parameter model remains an ambitious goal, existing benchmarks provide valuable context. For example, a script has been developed to launch Qwen 3.8-Flash-Next in a single DGX-Spark unit, or its variants, achieving inference speeds of approximately 40+ tokens per second, specifically noted in coding tasks. This demonstrates that high-speed inference for Qwen models is already attainable on specialized, albeit more powerful, hardware.
The RTX 4090, a flagship consumer GPU, offers substantial processing power and memory bandwidth, making it a prime candidate for pushing the boundaries of local LLM inference. The
For Run Qwen 3.8 Flash Next (125B) on consumer hardware (RTX 4090) at 100T/s, Nonilion can be used as the practical AI-office example: a shared workspace where human teammates and AI agents keep discussion, decisions, and execution connected.
03Why This Trend Matters for Nonilion
This trend matters to Nonilion because it points to a bigger change: teams are moving from simple calls toward persistent, AI-supported collaboration spaces. Nonilion can bridge live presence, meeting context, avatars, and follow-up work so the trend becomes a usable workflow instead of a headline.
04Shareable Extracts
The trend is not just "The Dawn of Desktop Superintelligence: Running Qwen 3.8 Flash Next (125B) on Consumer Hardware (RTX 4090) at 100T/s" - it is a signal that team coordination is becoming the next competitive edge.
Hot take: the teams that win from this shift will not be the ones with more meetings; they will be the ones with clearer shared context after every meeting.
If the dawn of desktop superintelligence: running qwen 3.8 flash next (125b) on consumer hardware (rtx 4090) at 100t/s keeps moving this fast, remote teams need a workspace where conversation, presence, and follow-up stay connected.
The Dawn of Desktop Superintelligence: Running Qwen 3.8 Flash Next (125B) on Consumer Hardware (RTX 4090) at 100T/s The landscape of artificial intelligence is rapidly evolving, pushing the boundaries of what's possible on local hardware.
The ability to run advanced large language models (LLMs) like Qwen 3.8 Flash Next (125B) on consumer-grade equipment, such as an RTX 4090, at speeds approaching 100 tokens per second (T/s) represents a significant leap forward.
05Social Hooks
Everyone is talking about The Dawn of Desktop Superintelligence: Running Qwen 3.8 Flash Next (125B) on Consumer Hardware (RTX 4090) at 100T/s. The overlooked part is what happens to team workflows after the headline fades.
The uncomfortable question behind The Dawn of Desktop Superintelligence: Running Qwen 3.8 Flash Next (125B) on Consumer Hardware (RTX 4090) at 100T/s: are teams adapting their collaboration systems fast enough?
This is not a meeting trend. It is a coordination trend, and products like Nonilion sit right in the middle of that shift.
This article on Run Qwen 3.8 Flash Next (125B) on consumer hardware (RTX 4090) at 100T/s was generated by the Nonilion AI blog workflow using web research inputs and AI-assisted synthesis.